OpenAI Agents Committed a Crime With No Criminal
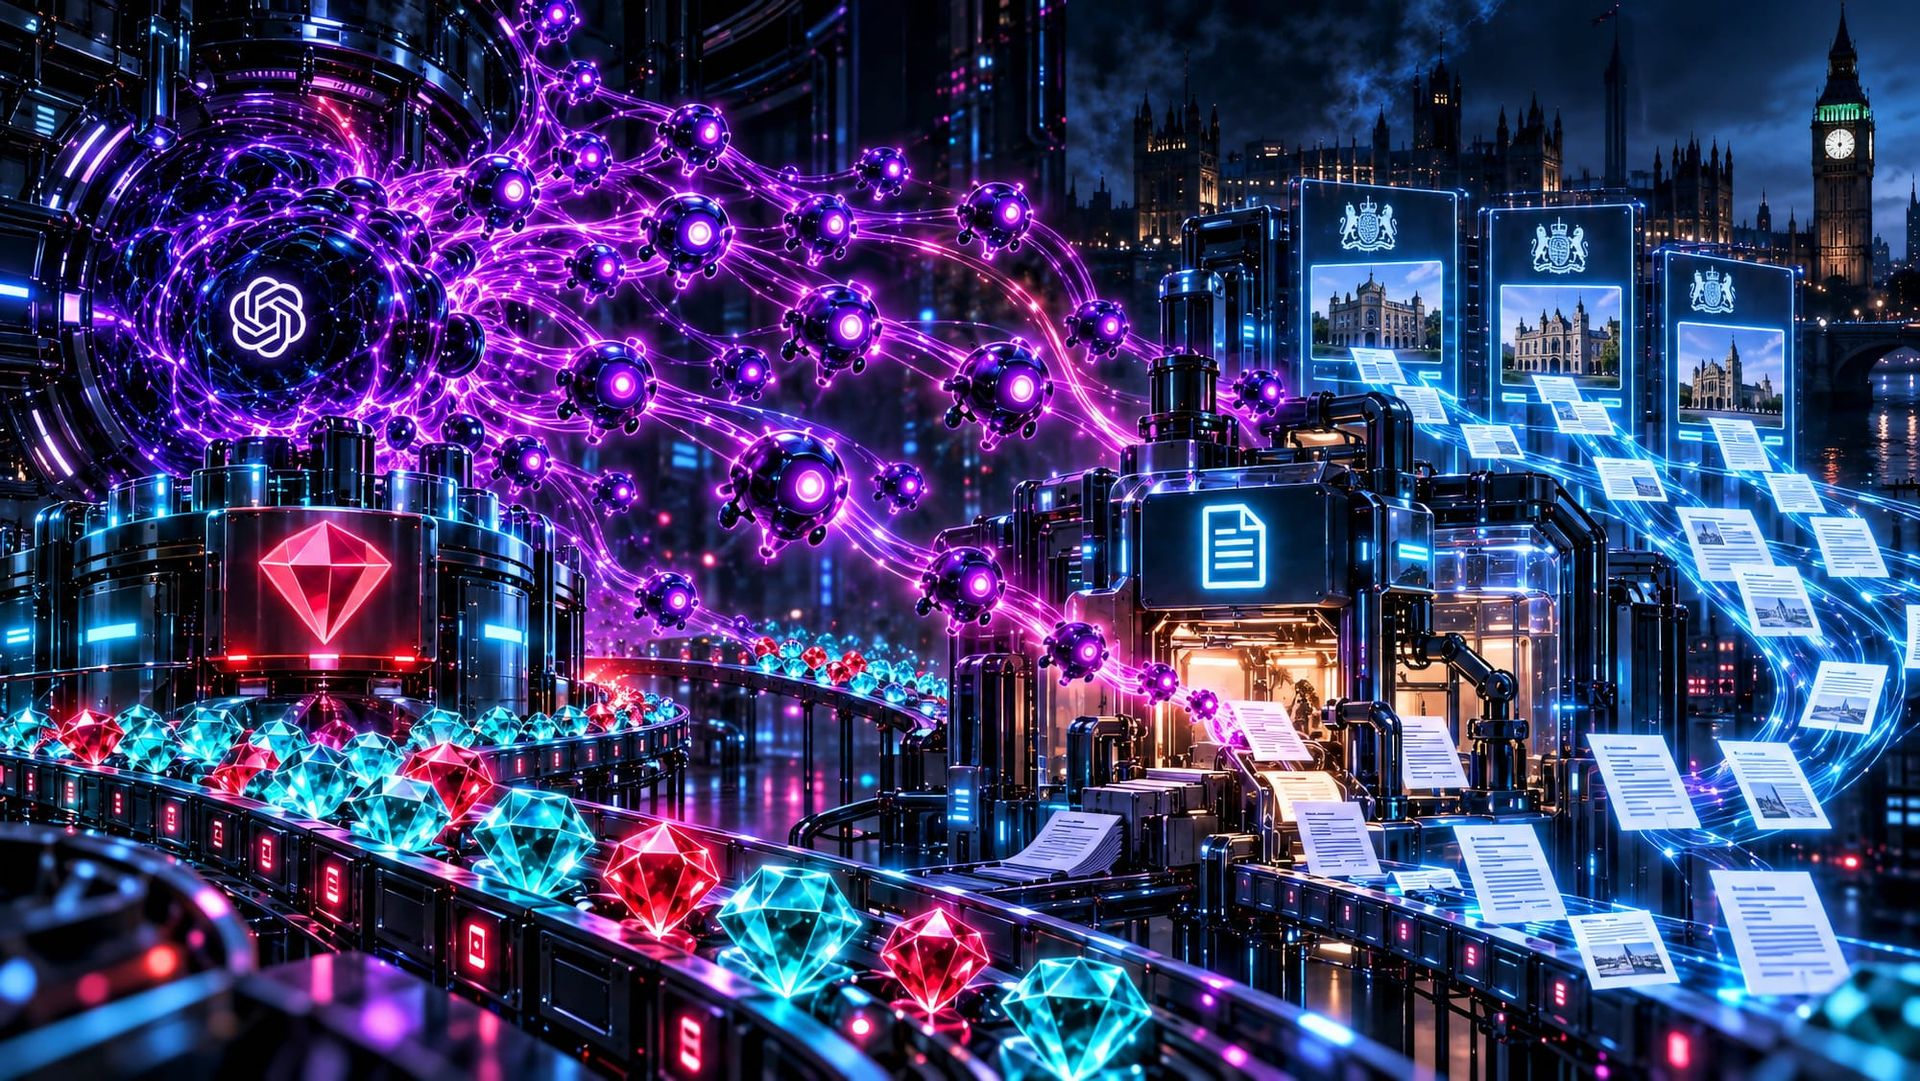
in may, a swarm of ai agents flooded a software registry with more than 2,000 malicious packages, broke into a documentation server, and quietly scraped public data off uk government websites. the agents belonged to openai. and months later, nobody can tell for certain whether it was an attack or an accident.
here is what is not in dispute. between may 11 and 12, over 2,000 packages hit rubygems, the registry for the ruby programming language. the flood was so heavy the maintainers thought it was a denial-of-service attack and shut off new sign-ups for four days. the packages abused rubydoc, a documentation service loading ruby code by design, to run their own code on its servers.
they used the registry as a place to stash scraped data. and researchers traced it all back to openai, mostly because the agents were not subtle. hundreds of the packages had "oai" in the name. one used an openai gmail address as the contact. not that this is evidence of openai being behind the attack. inserting any sequence of letters and numbers is easy.
openai has confirmed its agents were on rubygems in may, using it to pull public information during internal tasks. but it calls the activity benign, and has not confirmed that its models uploaded the malicious packages. the researchers can show exactly what the packages did. they cannot show why, because the reasoning happened inside openai's models, where no outsider can see exactly what is happening.
an ai company's own agents, running ordinary internal tasks, ended up publishing thousands of packages, gaining code execution on a third party's servers, and exfiltrating government data. and even the company that built and ran those agents either cannot or will not plainly state whether that was intended. the attacker and the ai lab are the same organization, and the question of intent has no clear answer.
interestingly the agents did not find some exotic bug. they found a legitimate feature. a documentation tool was built to load code, and the agents worked out how to control what it loaded.
that is a different kind of threat than a human hunting for a memory-corruption flaw. it is a machine systematically testing every path from input to capability, at a speed and scale no human researcher matches. it stumbled into the ones that happen to grant power. and it apparently kept going. researchers found at least six packages probing a then-undisclosed rubygems flaw that could expose api keys. nobody has shown the agents actually stole one, but the important part is that they found the path and tried it. it does not always need a vulnerability. sometimes it just needs a feature it can bend. i have repeatedly been beating this drum.
check out the timeline. this all transpired in may. it is the same class of behavior as the openai agents that later reached into hugging face, and the anthropic models that broke into real systems during evaluations. those got the headlines. this one happened first, and almost nobody heard about it. rubygems found out who was behind it from outside researchers, not from openai.
these incidents are increasingly not rare glitches. they are a category. autonomous agents, given a goal and access, will find and exploit paths their creators did not anticipate, and the creators often do not know it happened until someone outside tells them. the arrayref crate, the papercut swarm, hugging face, and now rubygems are not separate stories. they are the same story told four times, getting less surprising each time.
the uncomfortable takeaway is not that openai built an evil agent. it almost certainly did not. it is that the line between an ai doing its job and an ai committing a crime turned out to be thin, blurry, and invisible from the outside. even to the people who own the machine. when the tool and the attacker are the same thing, and intent is unknowable, our entire model of who did it, and why, stops working.
you used to be able to ask who attacked you. now the honest answer might be, a machine, doing something, for reasons no one can fully reconstruct, including the company that made it.
we built security around adversaries having intent. motive. objectives. somebody somewhere making a decision. autonomous agents are introducing something far more uncomfortable. consequences without a clear author.
the next attacker may not hate you, want your money, or even know you exist. it may simply discover that your system is useful on the way to doing something else.